White-label private AI · for GPU integrators

You deliver the cluster.
We deliver what runs on it.

Enclave is the white-label application layer that turns your hardware quote into a working private AI deployment — a fixed-price line item on your paper, delivered under your brand. You margin every deal. We never touch your customer relationship.

20%
resale discount
$25,000
fixed-price pilot
30 days
from readiness to working pilot

The stall

Everyone's warranty says the same thing: software not included

That's not a flaw — it's the right call for a hardware business. But it leaves your customer with a $30–100k system and nobody to make it do the thing they bought it for.

What the customer wanted

"Private ChatGPT on our documents. Our hardware, our building. Nothing leaves." — and Enclave answers it with OpenAI's own open-weight model, gpt-oss-120b, served on the box you deliver.

What the free stack delivers

The NVIDIA RAG Blueprint gets them a strong pilot — by design. Its interface is a sample for evaluation, and identity, document permissions, and connectors are left to the application layer. Someone still has to build that layer.

What happens next

The box underdelivers, a freelancer half-finishes it, and the customer remembers who sold them the hardware.

Enclave is the layer that monetizes what your warranty disclaims.

Built, not promised

The platform exists. You can watch it run.

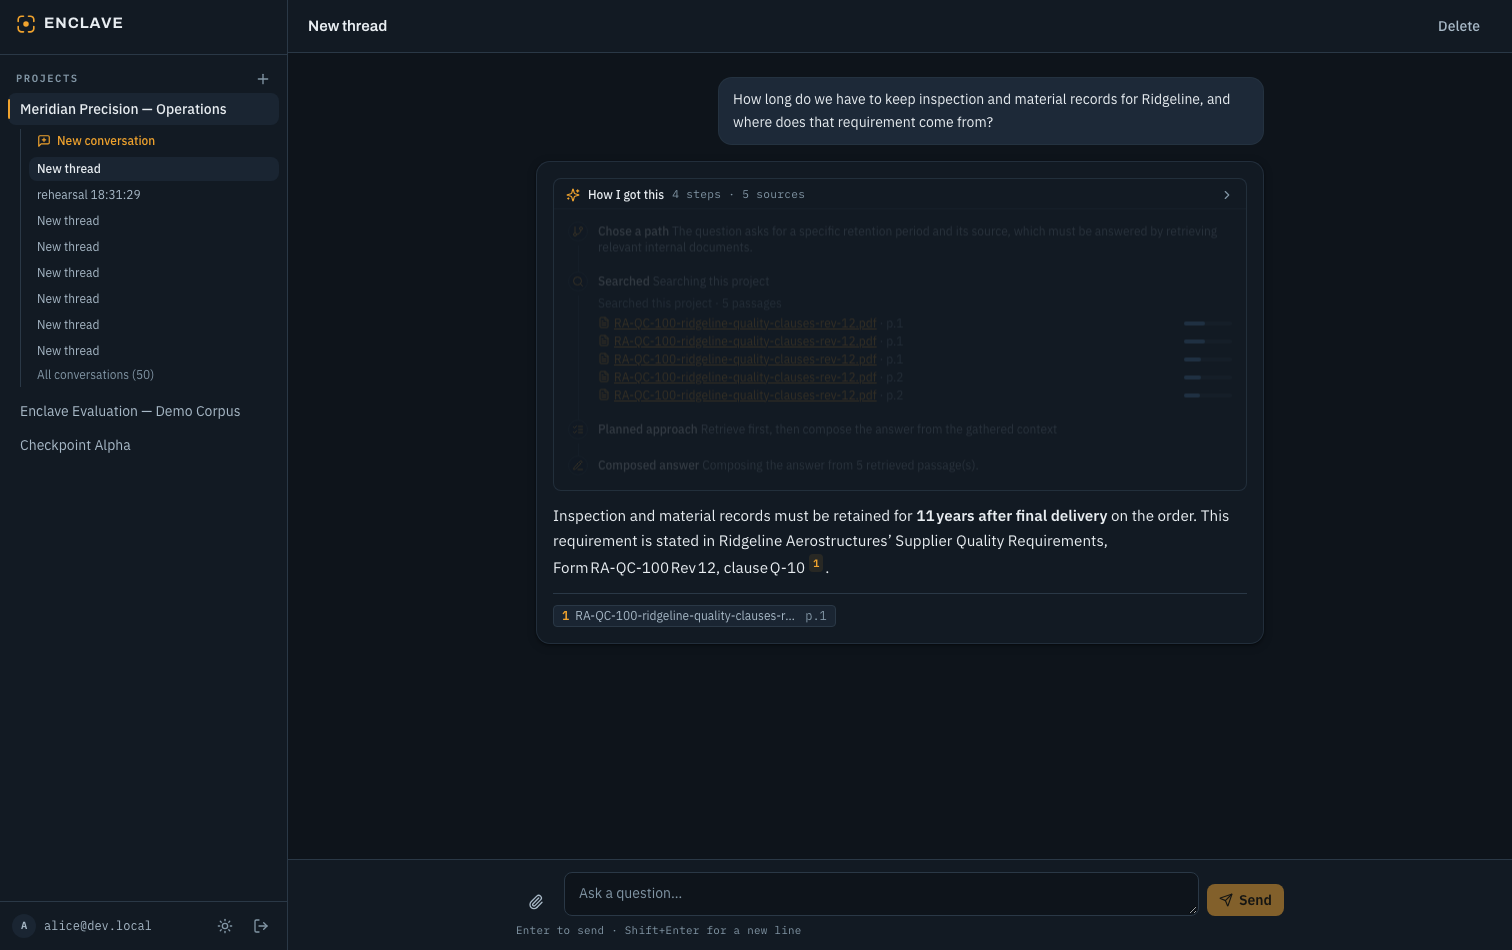
This isn't a services pitch with a deck. Enclave is a built platform — four hardened services, 3,500+ automated tests, a scored evaluation harness — and the live demo shows sign-in, document sync, permission-scoped cited answers, sandboxed data analysis, and audit export. Self-hosted deployments run model inference on the customer’s GPUs; laptop demonstrations may use hosted inference.
enclave — your-customer.internal
The Enclave chat application answering a records-retention question with a cited answer and an expandable execution trail showing the steps and sources consulted.
The product your customer logs into — under your brand, on your delivered hardware. Demo environment, fictional corpus.
What ships in a pilot

Branded chat application, single sign-on against the customer's identity provider, role-based access, cited answers with a visible execution trail, guardrails, admin training.

What production adds

SharePoint sync with configured document permissions, plus file-system ingestion, ingestion tuned on the real corpus, an evaluation gold set, monitoring, backup/restore runbooks, admin console with audit export.

Factory pre-image

The platform installs at your integration bench, so the box ships working. Data onboarding happens after delivery, remotely, inside the customer's network.

And it is more than a chat window on a vector search. The application brain is a LangGraph supervisor loop that routes every turn — retrieval, sandboxed computation, or live systems — and calls the stock NVIDIA RAG Blueprint as its retrieval engine. This is the layer between the cluster you deliver and the outcome your customer bought:
needs documents

needs computation

needs a live system

passages gathered

charts + tables gathered

results gathered

no retrieval needed

enough gathered

/v1/search

turn starts

supervisor
routes with a structured decision:
rag · code · tools · respond · synthesize

rag agent
permission-scoped search
via the Blueprint

code agent
plan → script → locked
Docker sandbox

tools agent
typed tools + MCP servers

respond

synthesize
composed answer with
inline citations

streamed to the user

NVIDIA RAG Blueprint
(Diagram 1, stock)

Runs on the hardware you quote, under your brand. The Blueprint stays stock — your NVIDIA story and your customer's NVIDIA AI Enterprise entitlement carry straight through. Full walkthrough on the Built on NVIDIA page.

Two UX in one SKU

A destination app — and a copilot inside the ones your customer already has.

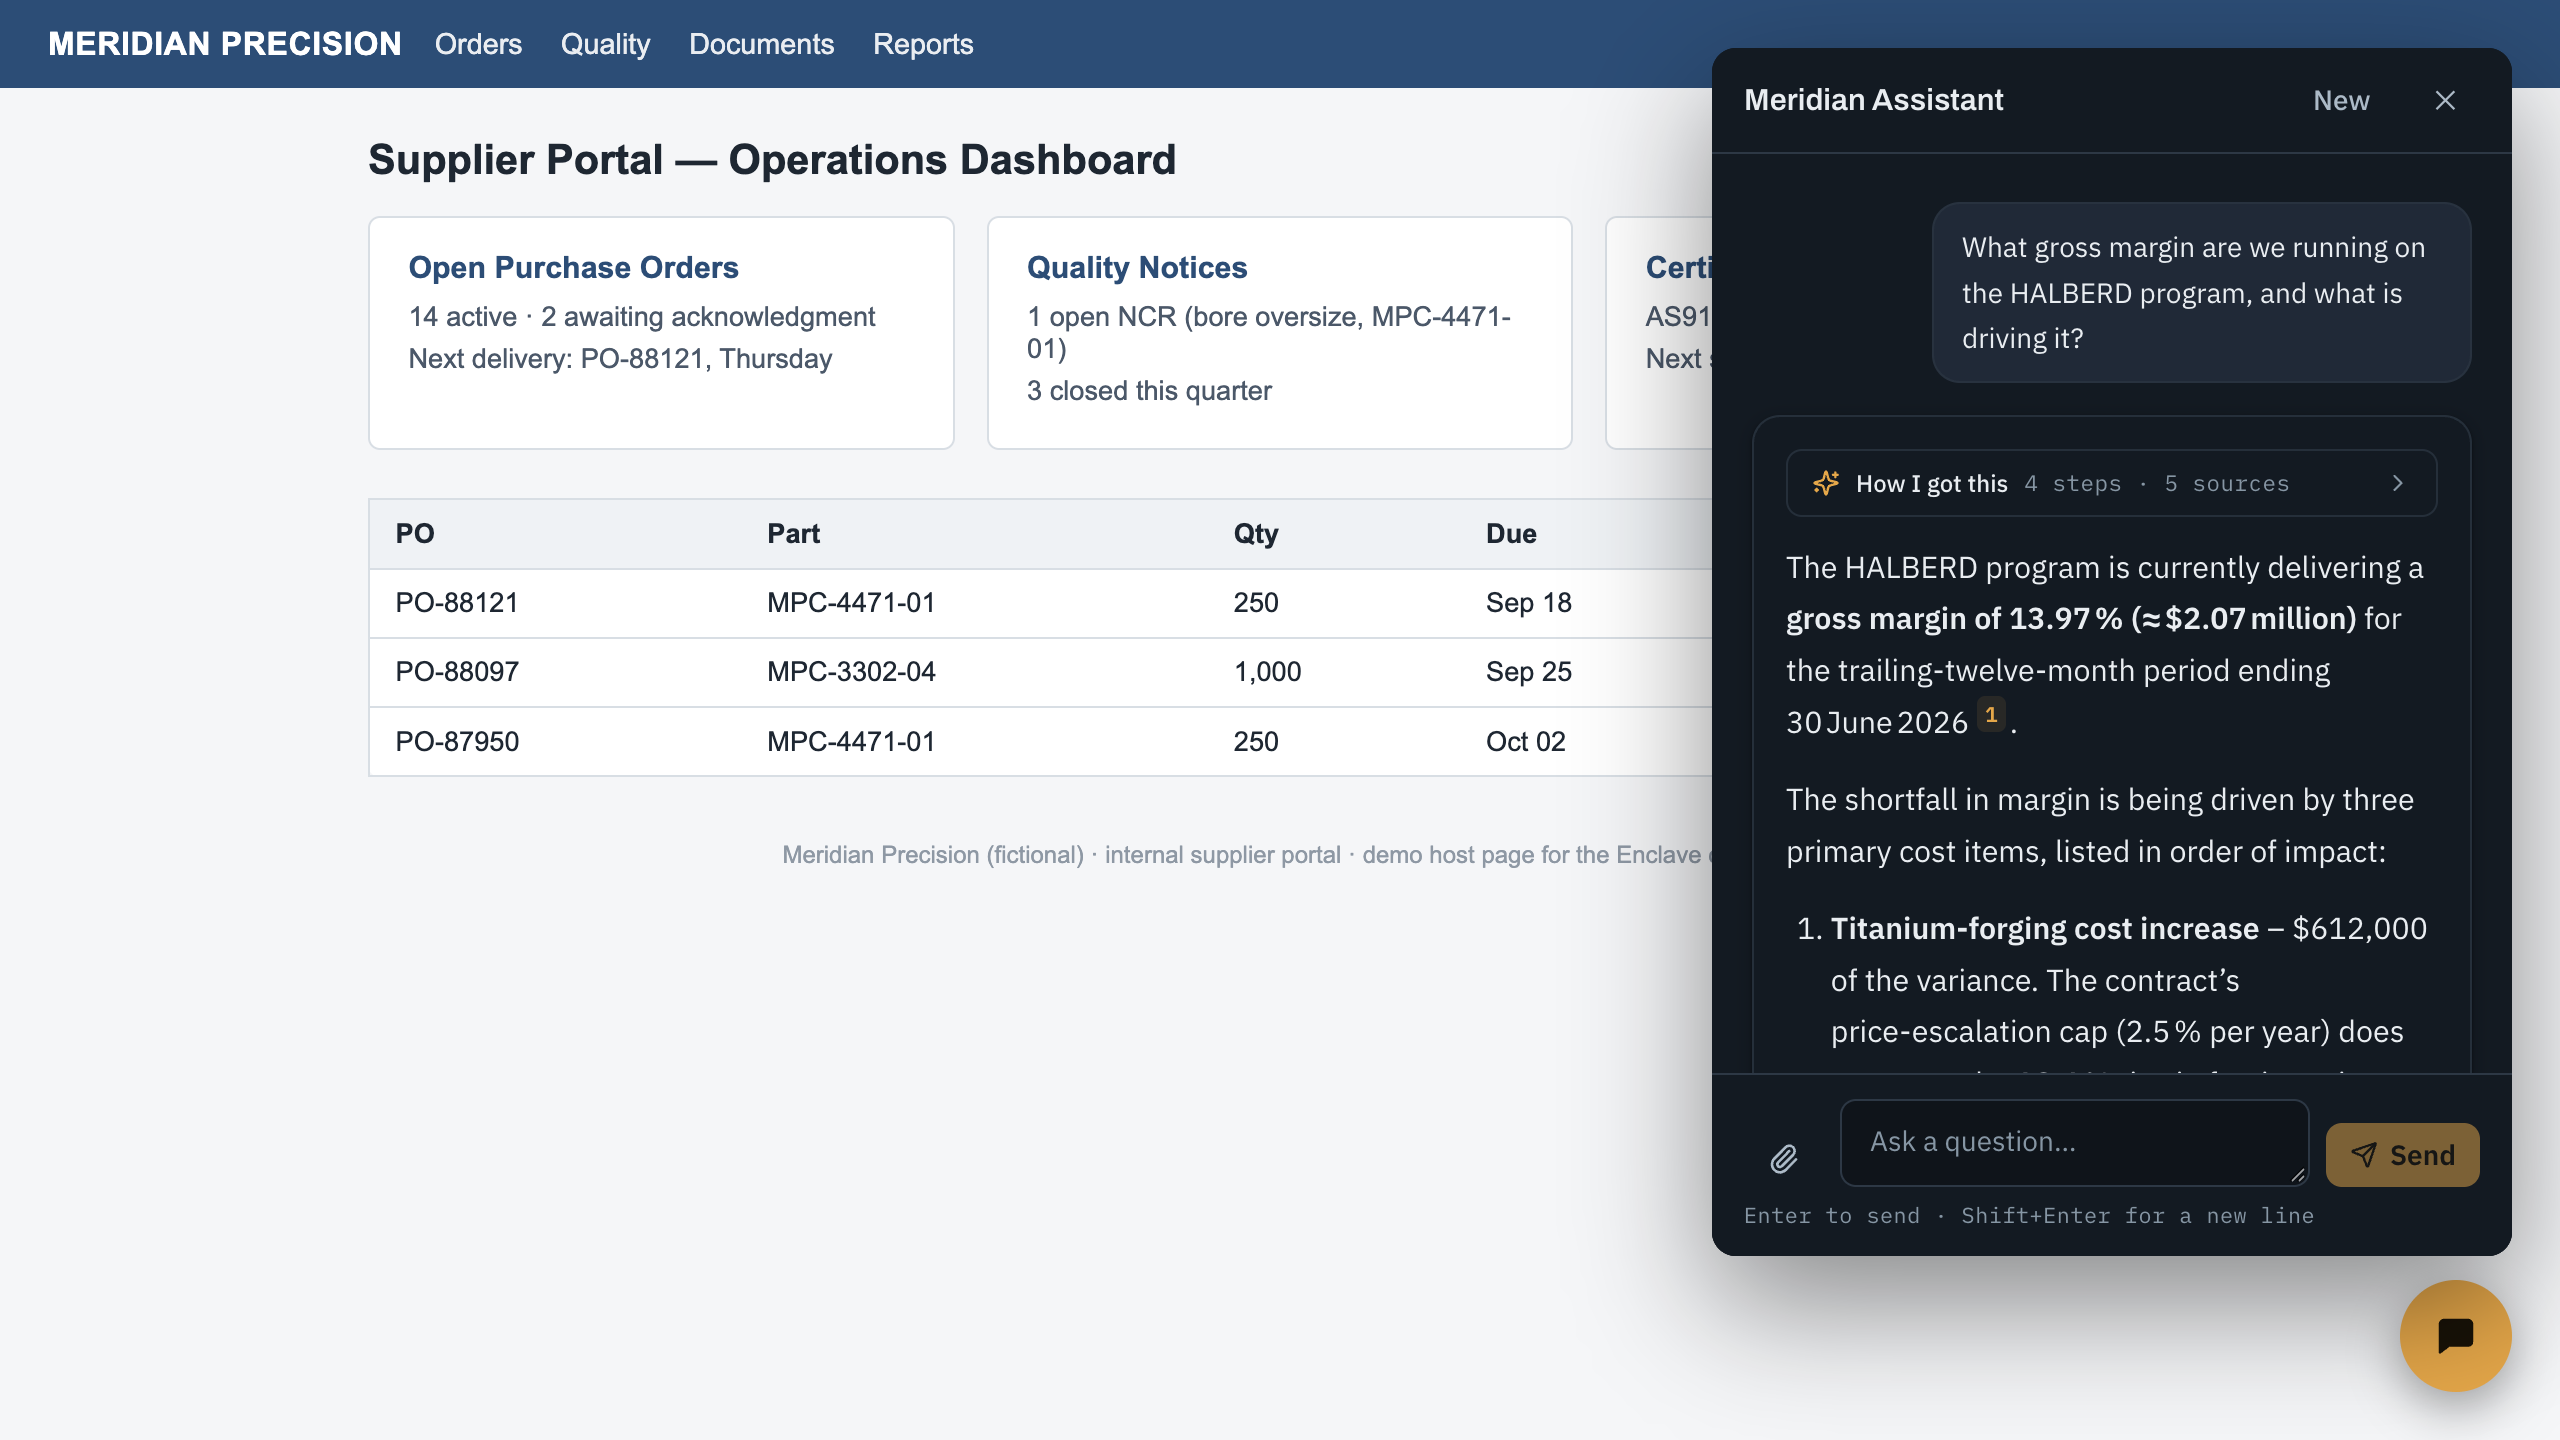
Every deployment ships two interfaces to the same governed platform: the full branded workspace, and an embedded copilot that drops into the customer's compatible internal web applications — intranet, ERP portal, dispatch console — with a two-line script paste. Same sign-on, same permissions, same audit trail; appearance is managed centrally from the admin settings page.

<script src="https://enclave.customer.internal/embed/enclave-copilot.js"
        defer data-project="PROJECT_ID"></script>

For your reps, that's a second demo moment: not just a new application beside the customer's systems, but AI appearing inside the portal the customer's people already use — a line that lands with buyers who have rolled out one-too-many new tools.

And it scales across departments without scaling the deal's complexity: one platform serves many segmented copilots — HR, engineering, finance — each bound to its own datasets, with every user's retrieval filtered by their directory groups on every request. Department segmentation is admin configuration, not a change order.

supplier-portal.customer.internal
A customer's own supplier portal with the Enclave copilot embedded, answering a program-margin question with a cited, permission-scoped answer — the page is the customer's app, only the copilot panel is Enclave.
Running on 2× NVIDIA RTX PRO 6000 — the copilot answers inside the customer's own portal, cited and permission-scoped, from a model served entirely on the delivered hardware. Demo environment, fictional company.

The SKU

A line item your reps can type today

QUOTE LINE ITEMENC-PILOT-25
Private AI Pilot — branded chat-with-your-documents on the delivered system. One corpus · SSO · 25 users · working in 30 days from readiness.
$25,000 fixed  ·  requires ENC-ASSESS ($2,500, credited)  ·  never gates the hardware PO

Separable line item — the customer can strike it and the box still ships. Or attach it as a scripted follow-up two weeks after ship notification. Your reps choose per deal.

PackageWhat the customer getsPrice
Assessment
mandatory first step
Corpus survey, permission-model review, sizing, written findings + firm quote$2,500 (credited)
PilotSingle box (2× NVIDIA RTX™ PRO 6000-class), one corpus, branded chat UI, SSO, ≤25 users, guardrails, training, scored acceptance demo. Pre-priced Production option: 60 days, 50% pilot credit$25,000 fixed
Production+ SharePoint sync with configured document permissions, plus file-system ingestion, ingestion tuning on the real corpus, evaluation gold set, monitoring, runbook, admin console$55–95k fixed-scope
Managed AIPatching, model refreshes, index maintenance, quarterly quality report, next-business-day support$3.5–4.5k / mo

NVIDIA edition

Built on the NVIDIA RAG Blueprint: NVIDIA NIM™ microservices, NVIDIA NeMo™ Retriever embedding and reranking, guardrails, GPU-accelerated hybrid search — under an NVIDIA AI Enterprise subscription. For compliance-driven buyers who need the supported-stack story — and you resell the per-GPU NVIDIA AI Enterprise licenses for additional margin on every deployment.

Partner economics

Add $5,000 gross to a $25k pilot. Enclave delivers.

$3,000
Your gross today: $30k workstation at 10% margin
+$5,000
Resale gross on the $25k pilot (20%) — on your paper, delivered by Enclave
$750
Flat SPIF to your rep, per registered services deal, paid on customer PO

"For buyers whose data can't touch the cloud — CUI and DFARS 7012 environments, no-cloud-AI policies, air-gapped networks — cloud assistants aren't on the menu. And a cloud assistant never sold anyone a box."

WHY THIS SKU EXISTS

Why us

Built and proven where the stakes were highest

Enclave's founder, Rian Sousa, architected the initial end-to-end design of a U.S. state treasury's private AI platform and worked with a team to develop it from scratch: multi-agent RAG over sensitive financial data, local models, enterprise SSO and role-based access control, zero-trust architecture, Kubernetes. The architecture evolved as the team grew and the scope expanded. Enclave is an independent, AI-native product built from the ground up on the NVIDIA RAG Blueprint — the experience without the baggage.

Next step

One call. Bring an open hardware deal — we'll show you the attach.

20 minutes with the founder, including the live demo. If it's not a fit for your quote flow, you'll know by minute ten.

Book a partner call